

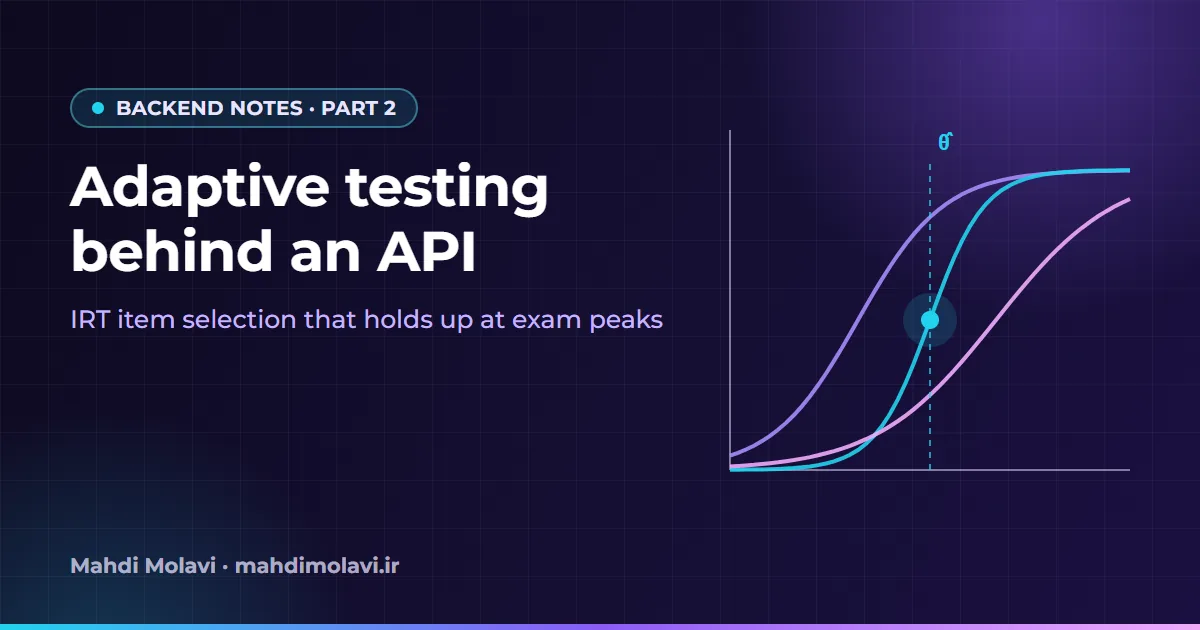
A fixed exam asks every student the same forty questions. Strong students spend most of their time on questions that tell you nothing new about them, and weaker students spend theirs on questions they have little chance of answering. An adaptive test does something smarter. After every answer it updates its estimate of the student's ability and picks the question that will be most informative at that estimate. The usual result is the same precision with fewer questions.
At NovaTech I architected an IRT-based adaptive testing platform for personalized assessments and analytics, serving about 89,000 students. This note covers the model briefly and then the part that interests me most as a backend engineer: putting the select, answer, update loop behind an API that stays responsive when an exam window opens and everyone starts at once.
IRT in five minutes
Item response theory models the probability of a correct answer as a function of a latent ability, written θ (theta), and a few parameters of the item. Ability lives on a standardized scale: θ = 0 is roughly the average of the calibration population, and most students fall between −3 and 3.
- 1PL (Rasch): one parameter per item, its difficulty b. P(correct) = 1 / (1 + e−(θ − b)), so at θ = b the chance is 50%.
- 2PL: adds a discrimination a, which controls how sharply the curve rises around b: P = 1 / (1 + e−a(θ − b)).
- 3PL: adds a lower asymptote c for guessing, which suits multiple-choice items: P = c + (1 − c) / (1 + e−a(θ − b)).
Some texts multiply the exponent by a scaling constant D ≈ 1.7. Either convention works, as long as the service uses the same one as the calibration that produced the parameters.
The idea that drives adaptive selection is item information. Each item measures well in one region of θ and poorly elsewhere. For the 2PL model, I(θ) = a² P(1 − P), which peaks at θ = b. For the 3PL, I(θ) = a² · ((P − c) / (1 − c))² · (1 − P) / P. Information adds up across items, and the standard error of the ability estimate is roughly 1 / √(total information). Picking items that are informative at the student's level shrinks the error fastest.
Item parameters come from calibration, which fits the model to responses from earlier administrations. That is an offline statistical job, and Python is a natural home for it. New items need parameters before they can be selected, so a common practice is to embed them, unscored, in live tests until enough responses exist. The online service only consumes the results.
The loop
- Start with a prior belief about θ, usually a standard normal.
- Select the next item from the current estimate, the items already shown and the test's content rules.
- Answer: the student responds, and the response is stored durably.
- Update the ability estimate with the new response.
- Stop when the standard error falls below a target or the test reaches its maximum length; otherwise go back to step 2.
For the update I like EAP (expected a posteriori) estimation on a fixed grid of θ values. Maximum likelihood is the textbook choice, but it has no finite answer when a student has answered everything right, or everything wrong, which is often the situation after the first few items. EAP uses the prior to stay finite, and on a grid it is plain arithmetic. It is also incremental: the posterior after n answers is the posterior after n − 1 answers times one likelihood curve, so this part of the session state is a single array.
public sealed record Item(int Id, double A, double B, double C, string Area);

public static class Irt
{
    public static double P(Item item, double theta) =>
        item.C + (1 - item.C) / (1 + Math.Exp(-item.A * (theta - item.B)));

    public static double Information(Item item, double theta)
    {
        var p = P(item, theta);
        var x = (p - item.C) / (1 - item.C);
        return item.A * item.A * x * x * (1 - p) / p;
    }
}

public static class Eap
{
    // 61 quadrature points from -4 to 4
    public static readonly double[] Grid =
        Enumerable.Range(0, 61).Select(i => -4 + i * 8.0 / 60).ToArray();

    public static double[] Prior() =>
        Normalize(Grid.Select(t => Math.Exp(-0.5 * t * t)).ToArray());

    public static double[] Update(double[] posterior, Item item, bool correct)
    {
        var next = new double[Grid.Length];
        for (var i = 0; i < Grid.Length; i++)
        {
            var p = Irt.P(item, Grid[i]);
            next[i] = posterior[i] * (correct ? p : 1 - p);
        }
        return Normalize(next);
    }

    public static (double Theta, double Se) Summarize(double[] posterior)
    {
        double mean = 0, variance = 0;
        for (var i = 0; i < Grid.Length; i++) mean += Grid[i] * posterior[i];
        for (var i = 0; i < Grid.Length; i++) variance += Math.Pow(Grid[i] - mean, 2) * posterior[i];
        return (mean, Math.Sqrt(variance));
    }

    private static double[] Normalize(double[] w)
    {
        var sum = w.Sum();
        for (var i = 0; i < w.Length; i++) w[i] /= sum;
        return w;
    }
}
Normalizing after every answer keeps the values in a comfortable numeric range however long the test runs. The grid size is a trade-off. Sixty-one points between −4 and 4 is a sensible starting point; before paying for a finer grid, check whether it changes any final scores.
Choosing the next item
The textbook rule is maximum information: pick the unused item with the highest I(θ̂) at the current estimate. Used naively, it has two problems that matter in production.
Exposure. Maximum information keeps choosing the same few high-discrimination items. A large share of students sees them, they leak, and the rest of the bank sits idle. Common remedies are randomesque selection (choose at random among the top k), Sympson-Hetter exposure control (each item gets an administration probability tuned by simulation), and a-stratification (use low-discrimination items early, while θ is still uncertain, and save the sharp ones for later).
Content balance. A maths test that measures θ precisely but never asks about geometry is not a valid maths test. The simplest approach, in the spirit of Kingsbury and Zara's constrained CAT, chooses the content area furthest below its target share first and only then maximizes information within it. Heavier machinery exists, such as van der Linden's shadow tests, which solve an optimization problem at every step, but the simple version goes a long way.
public sealed class ItemSelector(IReadOnlyList<Item> bank, IReadOnlyDictionary<string, double> targets)
{
    public Item? Next(double theta, IReadOnlySet<int> used,
                      IReadOnlyDictionary<string, int> givenPerArea, int topK = 5)
    {
        var total = Math.Max(1, givenPerArea.Values.Sum());

        // 1. content balancing: the area furthest below its target share that still has items
        var area = targets
            .OrderByDescending(t => t.Value - givenPerArea.GetValueOrDefault(t.Key) / (double)total)
            .Select(t => t.Key)
            .FirstOrDefault(a => bank.Any(i => i.Area == a && !used.Contains(i.Id)));
        if (area is null) return null;

        // 2. maximum information within that area, 3. randomesque exposure control
        var candidates = bank
            .Where(i => i.Area == area && !used.Contains(i.Id))
            .OrderByDescending(i => Irt.Information(i, theta))
            .Take(topK)
            .ToList();
        return candidates[Random.Shared.Next(candidates.Count)];
    }
}
This is a linear scan over the bank, and for a few thousand items it costs far less than a single network round trip. If profiling ever says otherwise, compute every item's information at every grid point once, when the bank loads, and selection becomes a lookup at the nearest grid index.
Caching the item bank
Item parameters are small and change rarely: a few numbers per item, plus a content area and status flags. That makes them ideal for an in-process cache. Each API instance holds the active bank in memory as an immutable object tagged with a bank version. Publishing a new calibration writes rows in SQL Server, bumps the version, and tells the instances to reload, through a Redis key they poll or a pub/sub message. Instances swap the reference atomically, so a request already in progress finishes with the bank it started with.
Two rules keep this safe. A session records the bank version it started with, so no student is scored with parameters from two calibrations; that means keeping the previous version loaded until its sessions finish. And item text and answer keys are not part of this object. They are fetched only for the item being shown, and the key never leaves the server.
API shape
| Endpoint | Purpose |
|---|---|
POST /sessions | Start a test: create the session state (prior, empty history, bank version) and return the first item. |
POST /sessions/{id}/responses | Submit an answer. The response carries the next item, or a completion signal. |
GET /sessions/{id} | Resume after a reconnect: return the current item without advancing. |
GET /sessions/{id}/result | Score and report, once the session is complete. |
Returning the next item in the answer's response saves one round trip per question, which adds up over a test and over a peak. The answer endpoint must also be idempotent. On a flaky mobile connection the client will retry, and a retried answer must not be counted twice or advance the test twice. A unique constraint on (session, item) in SQL Server, plus returning the already chosen next item when a duplicate arrives, handles this cleanly.
Staying responsive at exam peaks
The arithmetic of IRT is cheap: one EAP update over 61 points and one pass over the bank are a small amount of CPU work, far less than a database round trip. What decides whether the system holds up is everything around the math. On the NovaTech platform I built the assessment creation, scoring, reporting and item-selection workflows, and they had to hold up during peak exam periods. The principles I follow for this kind of service:
- No database reads on the selection path. The bank is in memory, and session state (posterior, used items, area counts) lives in Redis with a TTL longer than the test. Each answer costs one durable write and one small state update.
- Durable first, cache second. The response goes to SQL Server before the Redis state changes. If Redis loses a session, it can be rebuilt by replaying the stored responses through the same update function, one more reason to keep that function deterministic.
- Stateless API instances. Any instance can serve any request, so scaling out before an exam window only needs a configuration change.
- Heavy work off the request path. Reports and analytics are computed asynchronously after a session completes. A student waiting for the next question should never wait for somebody else's report.
- Warm up before the window opens. Load the bank, confirm every instance runs the same version, and run a load test with realistic think times well before exam day.
Scoring deserves one last remark. The final θ is on the calibration scale, and nobody wants to see a score of −0.37. Map it to a reporting scale, and show the standard error as a range instead of pretending the number is exact.
If you are planning an adaptive or high-traffic assessment system, this is the kind of backend work I take on. The next note steps back from the domain to the code itself: how I structure a real .NET service with Minimal APIs.
This note is also available in Persian: read the Persian version.