Part 3 ended with a specific diagnosis. The local estimator puts a Normal prior with standard deviation 0.1 on both discrimination and difficulty. On a fixed set of 30 questions, its estimates rose steadily as students were added. And widening only the discrimination prior, on one unchanged response set of 523 people, moved the maximum a from about 0.934 to about 2.637. Once you have seen that, the next move is to try a different estimator and check whether the dependence on sample size goes away.
Two candidates were close at hand. The local library already contains a hierarchical branch that learns its item priors from the data. GIRTH, an independent open-source Python library, fits the same 2PL response function by marginal maximum likelihood. I tried both. Each answered part of the question and opened a new one, and on the evidence collected so far neither is a drop-in replacement for the production estimator.
The hierarchical branch changes the model and the guide
In Pyro, the model is the generative story (priors plus likelihood) and the guide is the variational family that approximates the posterior during stochastic variational inference. The Pyro SVI tutorial explains the split well. The local 2PL class has a model_hierarchical and a matching guide_hierarchical, and selecting the hierarchical option switches both. I spell this out because it is easy to describe the experiment as a change of guide only, and that description would be wrong. The prior changes too, and the guide changes to match it.
Where the fixed branch holds the item priors at N(0, 0.1), the hierarchical branch learns broad location and scale hyperparameters. That loosens the pull toward zero, and it also lets the latent scale move. In a 2PL model the likelihood only sees the product a(θ − b). Flip the signs of θ, a and b together and every predicted probability stays the same. Multiply θ and b by a positive constant and divide a by that constant, and again nothing observable changes. Something in the setup has to fix the direction and the unit of the scale, and with learned hyperparameters that something is weaker.
In one small-sample hierarchical run the direction came out reversed. The fitted abilities ran against the students' empirical performance, and the discriminations reversed with them. Read naively, the raw output says the questions had suddenly become defective. The questions had not changed at all. This was an identification and orientation problem in the fit.
So before comparing any hierarchical run with a fixed-prior run, I made the orientation consistent with empirical performance and then expressed the coefficients per estimated ability SD:
theta_standardized = (theta - mean(theta)) / SD(theta)
a_standardized     = a * SD(theta)
b_standardized     = (b - mean(theta)) / SD(theta)
The orientation correction comes first and the rescaling second. Together they leave every modeled response probability where it was, which is why they are safe to apply within a single fit. They do not connect one exam's scale to another exam's scale. Part 6 comes back to that difference, because it is the central problem with comparing years.
One controlled comparison
The test bed was the controlled setting from part 3: the same 30 archive mathematics questions, fitted once on a 434-person subset and once on all 9,099 students with usable responses.
| Method | Mean a, standardized units, N = 434 | Mean a, standardized units, N = 9,099 |
|---|---|---|
| Fixed narrow-prior branch | 0.5874 | 1.1375 |
| Hierarchical branch | 1.4894 | 1.2896 |
These are standardized units, so do not read them against the raw means in part 3's table. Within this table, the fixed-prior mean rose by about 94% from the small subset to the full pool, while the hierarchical mean fell by about 13%. For this diagnostic, the hierarchical branch had a much smaller size effect.
That is as far as the result goes. A smaller effect is still an effect, it comes from one question set and one subset, and the full-data hierarchical run kept one negative discrimination even after the orientation correction. Earlier hierarchical trials had shown negative items and scale problems of their own. I left the branch labeled exploratory. Before it could be a production candidate it would need explicit identification constraints, a suitable way to model positive discrimination, fit checks, parameter recovery experiments and stability across repeated seeds. None of those were part of this work.
GIRTH: the same 2PL, estimated by marginal maximum likelihood
The second candidate was GIRTH 0.8.0 with its twopl_mml routine. The item response function stays 2PL. What changes is the estimation method: in place of the local variational Bayesian fit, marginal maximum likelihood integrates the likelihood over an assumed ability distribution and maximizes it with respect to the item parameters. This comparison therefore swaps the estimator and keeps the item model, which is a much larger change than renaming parameters or adjusting a constant in the old code.
I ran it on a fresh extraction of responses with this configuration:
- a fixed reference ability distribution N(0, 1), whose shape was not re-estimated;
- 61 quadrature points on [−6, 6];
- at most 200 iterations, with no lookup-table approximation;
- the item limits of this library version: discrimination in [0.2, 5] and difficulty in [−6, 6];
- unseen responses passed as explicitly missing, kept distinct from observed incorrect answers, following the coding described in part 2;
- questions with no usable responses, or with every response correct or every response incorrect, identified as nonestimable instead of being given a free estimate.
In illustrative form, the call is short. The work is in preparing the matrix and in reading the output carefully.
from girth import twopl_mml

# Illustrative sketch; the exact option keys live in the pinned study scripts.
# responses: items x students, unseen responses tagged as missing (never as 0)
# study_options: fixed N(0, 1) ability distribution, 61 quadrature points
#   on [-6, 6], at most 200 iterations, no lookup-table approximation
estimates = twopl_mml(responses, options=study_options)
# read discrimination and difficulty from the result, then flag any value
# that sits on a bound and any nonestimable question
All 34 applicable main-lesson groups in this six-exam study reached GIRTH's internal convergence condition. Together they held 885 item rows across lessons and exams, covering 825 distinct content items. No final estimate sat on the upper discrimination bound. One sat on the lower bound of a, and 18 sat on a difficulty bound. I flagged every one of them, because a value on a bound marks where the optimizer was stopped by a limit, and it is not an unconstrained estimate.
Larger maxima
Here are the fresh local-code and GIRTH maxima for the mathematics lesson of each of the six exams from part 1. Both columns are refits on this study's extraction. They are not copies of the stored production coefficients, and they are not the single-subset control from part 3.
| Exam | Usable mathematics students | Fresh local-code maximum a | GIRTH maximum a |
|---|---|---|---|
| Mathematics track, original 1405 form | 443 | 0.87 | 1.70 |
| Experimental Sciences, original 1405 form | 523 | 0.97 | 3.31 |
| Humanities, original 1405 form | 1,169 | 1.27 | 2.18 |
| Mathematics track, 1403 archive | 6,343 | 1.53 | 1.85 |
| Experimental Sciences, 1403 archive | 9,099 | 1.74 | 2.24 |
| Humanities, 1403 archive | 8,650 | 1.72 | 2.35 |
The usable counts again differ from official attendance (443 usable mathematics students against 434 attendees on the current Mathematics-track exam, for example), as part 2 explained. GIRTH's maximum is higher on every row. The gap is widest on the small current exams, where the local code's maximum stays below 1 on two of the three, and narrowest on the large archive exams.
Larger maxima prove nothing about accuracy on their own, since an estimator with inflated slopes would also produce them. The check I trusted more was prediction of responses the fit had never seen.
Held-out prediction
For each of the six mathematics lessons, I withheld 20% of the students before fitting. To score a held-out student's response to an item, that student's ability was inferred with the target response excluded, which reduced leakage of the answer being predicted into its own prediction. The score is conditional log loss, and lower is better.
| Exam | Held-out students | Local-code conditional log loss | GIRTH conditional log loss |
|---|---|---|---|
| Mathematics track, original 1405 form | 89 | 0.4782 | 0.4156 |
| Experimental Sciences, original 1405 form | 105 | 0.3375 | 0.2766 |
| Humanities, original 1405 form | 234 | 0.3286 | 0.2854 |
| Mathematics track, 1403 archive | 1,269 | 0.4023 | 0.3988 |
| Experimental Sciences, 1403 archive | 1,820 | 0.2361 | 0.2322 |
| Humanities, 1403 archive | 1,730 | 0.2369 | 0.2320 |
GIRTH had the lower loss in all six lessons. The difference was clear on the three small current exams and small on the archive exams. Two cautions apply. A percentage reduction in log loss is not the same percentage gain in classification accuracy, so I avoid quoting it that way. And this was one fixed random split per lesson. Without repeated cross-validation, I cannot say how much the gap would vary from one split to the next.
Three more checks
The first was quadrature. Raising the number of quadrature points to 121 and the iteration cap to 400 changed discrimination by less than 0.0005 at most across the six mathematics lessons, so the grid was not what produced the results.
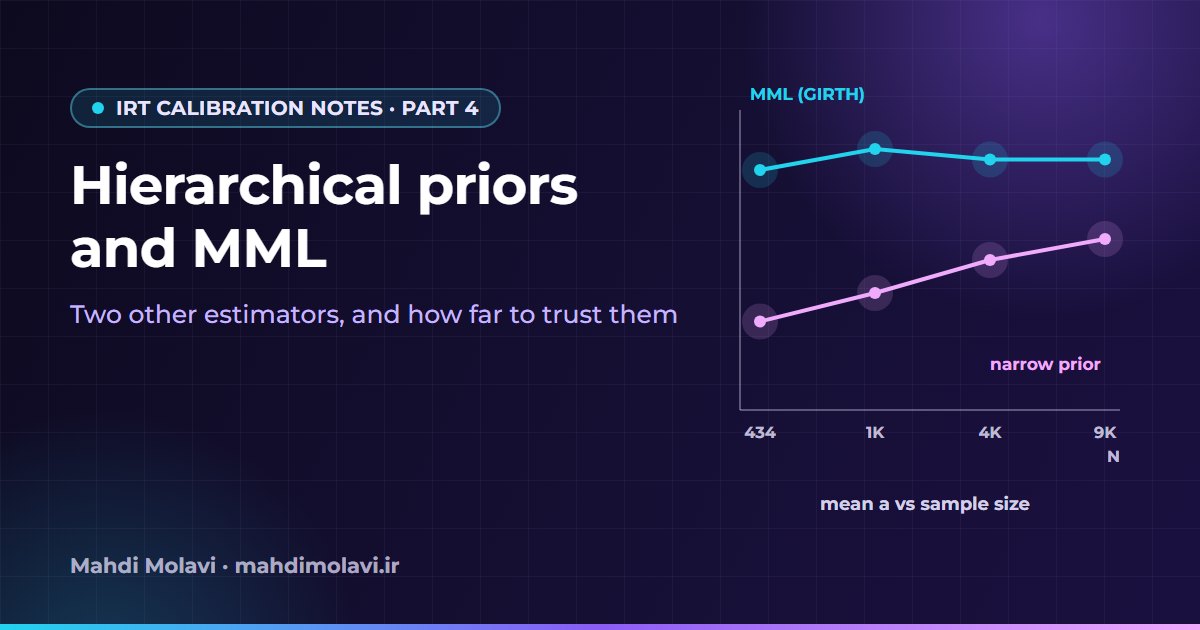
The second was size stability, on the same fixed archive mathematics questions used in part 3. Three GIRTH samples at N = 434 had mean a between about 1.51 and 1.76. At N = 1,000 the range was about 1.70-1.78, at N = 4,000 about 1.64-1.69, and the full fit on 9,099 students had a mean of about 1.67. Small samples still varied, their maximum a most of all, but the mean did not show the steady climb from low to high that the local code showed on these questions. A few samples per size is a small number, so I treat those ranges as rough.
The third was a bootstrap. I ran 100 student bootstraps for the 90 mathematics questions of the three current exams. The high-a item on the current Experimental Sciences exam had an approximate interval of 2.43-4.93 for a, and three of the 100 resamples hit the upper bound of 5. The interval is wide, and the bound hits mean its upper end partly reflects the library's limit.
One more distinction keeps the series honest. The small MML comparator that recovered high discrimination in part 3's simulation and the GIRTH evaluation here are separate implementations from separate phases. The simulation result belongs to the custom comparator on synthetic data, and the real-data results in this part belong to GIRTH.
Where the two alternatives stand
The hierarchical branch is an exploratory alternative with an open identification problem. GIRTH gives promising validation evidence for further work, and I would not call it a production migration. Boundary behavior, model misspecification, item invariance, repeated splits and the long-term work of maintaining a calibration all remain open. The maxima table and the held-out table are both measured against the local code on the same responses, which is useful. Neither measures against the truth, which nobody has for real exam questions.
My own reading is that the MML results are the most encouraging numbers in this investigation and also the easiest to oversell. On the same responses, a different estimator predicted held-out answers better in six mathematics lessons, with one split each. That does not make its higher coefficients true, and it does not tell anyone which questions are good.
Every comparison so far used one subset per size, or at most a few. Part 5 describes the study that replaced them with twenty nested samples per size across nine exams, and the engineering needed to make that run reproducible and restartable.
This note is also available in Persian: read the Persian version.